
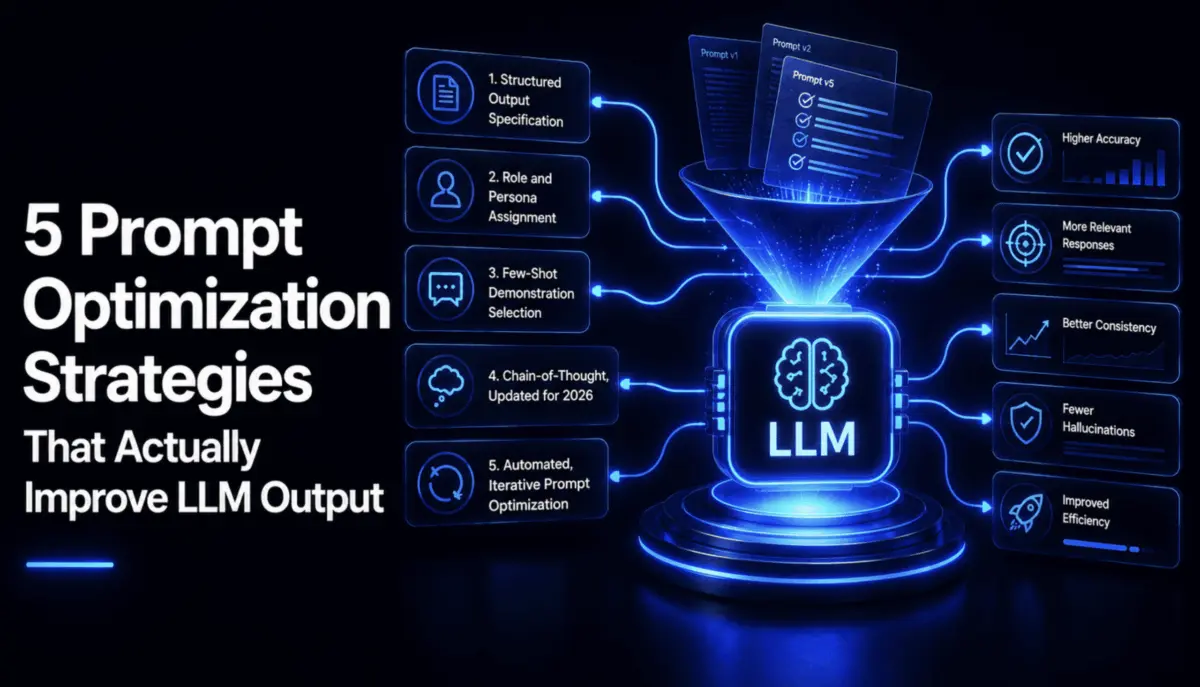
In the rapidly evolving landscape of artificial intelligence, the distinction between prompt engineering and prompt optimization has become a critical point of discussion for developers and software engineers navigating the practical limits of large language models. Industry practitioners frequently use the terms interchangeably, a habit that continues to generate unnecessary confusion across development teams. Prompt engineering primarily focuses on designing a prompt entirely from scratch, whereas prompt optimization addresses the refinement of an existing prompt through enhanced specificity, structural adjustments, and iterative testing, all without modifying the underlying model itself.
This differentiation carries weight in enterprise environments. Most professionals looking to elevate the quality of their large language model outputs are not staring at a blank page; they are working with a functional prompt that falls short of production standards. Rather than employing theoretical frameworks, they need to understand which targeted adjustments to an existing prompt genuinely alter performance and which modifications merely offer the illusion of improvement.
Technical writer and software engineer Shittu Olumide recently addressed this gap by outlining five specific prompt optimization strategies backed by analytical methodologies rather than anecdotal adjustments. To demonstrate their effectiveness, the strategies were tested against a single, deliberately complex dataset: a messy, multi-person meeting transcript that requires accurate conversion into a clean list of actionable items.
The benchmark transcript features three participants navigating conversational ambiguities, mid-sentence reversals, and unresolved assignments. These elements pose a significant challenge for automated extraction tools. For instance, a mobile layout review is initially assigned to one participant before being reassigned to another mid-discussion. Simultaneously, a separate tablet-breakpoint check is folded into that same review rather than tracked as an independent task. Furthermore, the responsibility for triaging a backlog of support tickets is explicitly left unresolved rather than quietly dropped or arbitrarily assigned by the model.
Standard prompts often manage the straightforward elements of such transcripts while failing on these nuanced details. An output that looks acceptable at a glance but mismanages these specific transactional anomalies fails in production, highlighting the necessity of rigorous prompt optimization.
Specifying Structured Output
The most quantifiable lever available in prompt refinement is the insistence on structured output, moving away from unstructured prose that resists automated parsing. While asking a model to list action items in natural language yields a fluent, readable response, it produces data that downstream systems cannot reliably ingest. In production workflows, unparseable output represents a critical system failure rather than a minor inconvenience.
When developers validate raw model outputs against explicit schemas using validation libraries like Pydantic, the limitations of conversational prose become immediately apparent. Standard prose responses fail validation checks because narrative text cannot substitute for structured formats regardless of its readability. Conversely, requests guided by explicit schemas parse cleanly into validated data objects.
This establishes the fundamental value of structured-output prompting: it provides the dividing line between human-readable text that requires manual transcription and machine-usable data that integrates directly into downstream software pipelines.
Assigning a Role and Persona
Beyond technical schemas, assigning a specific persona alters how a model activates its underlying training data for a given task. This practice consistently yields more context-aware outputs than generic instructions alone. It represents a subtle adjustment with measurable effects that incurs no computational overhead during testing.
Generic directives such as extracting action items from a transcript fail to account for conversational anomalies. In contrast, role-based prompts prime the model to anticipate human communication patterns, such as mid-sentence reversals, shifting assignments, and unconfirmed owners.
By framing the model as an experienced executive assistant familiar with the chaotic nature of corporate meetings, developers can prime the system to handle conversational ambiguity before it begins processing the text. This contextual priming proves especially valuable when handling complex transcripts where a superficial initial pass would inevitably miss critical adjustments.
Selecting Few-Shot Demonstrations
Research into prompt optimization indicates that demonstration selection strategies can exert a greater influence on output quality than the phrasing of the instructions themselves, with combined approaches outperforming either method in isolation. However, the critical factor lies not simply in adding examples, but in selecting the correct ones. Providing multiple variations of the exact same pattern offers the model minimal new information.
To maximize the value of few-shot demonstrations, developers can employ diversity-aware selection algorithms, such as utilizing term frequency-inverse document frequency vectorizers and cosine similarity metrics. This approach identifies candidate examples that are maximally dissimilar from one another, ensuring the demonstration set covers distinct structural patterns rather than near-duplicates of a single scenario.
When applied to administrative extraction tasks, an effective few-shot portfolio should incorporate scenarios with confirmed owners, explicitly unresolved assignments, and tasks that merge into existing items. This variety exposes the model to multiple authentic patterns rather than repeated iterations of uncomplicated cases.
Prompting for Chain-of-Thought
Chain-of-thought prompting, which encourages models to reason step-by-step prior to generating a response, continues to occupy a strategic role in prompt refinement, though its application has evolved. Frontier models now feature native reasoning capabilities, reducing the necessity of explicit step-by-step instructions compared to earlier iterations of generative models.
Nevertheless, explicit reasoning prompts retain their value when confronting genuine ambiguity, such as tracking ownership reassignments across a fragmented dialogue. Without prompted reasoning, a model may anchor onto the initial mention of an assignment and overlook a subsequent correction.
By directing the model to trace ownership across the entire conversation and report only the final confirmed owner, developers can force the system to evaluate the complete context rather than pattern-matching against the first plausible assignment. For cost-conscious deployments, emerging variants like chain-of-draft prompt the model to articulate reasoning steps in concise phrases, matching traditional accuracy while consuming a fraction of the reasoning tokens.
Running Automated, Iterative Prompt Optimization
The most advanced approach to prompt refinement involves shifting from manual intuition to automated, scored search processes. Rather than adjusting prompts by trial and error, developers can evaluate candidate instructions against comprehensive test suites to identify optimizations that genuinely improve performance.
Production-grade automated optimization tools generate prompt variations, score each iteration against real-world test cases, and retain successful modifications through hill-climbing search algorithms. The evaluation phase relies on fuzzy task-matching against known ground truths, measuring metrics such as recall, owner attribution accuracy, and penalties for fabricated information that lacks grounding in the source text.
Empirical evaluations demonstrate that automated search processes can efficiently isolate the minimum effective instructions required to reach optimal performance. By avoiding the tendency to overload prompts with redundant instructions, automated optimization provides a systematic method for achieving reliability in complex language model deployments.
The integration of these methodologies transforms prompt optimization from an intuitive exercise into a disciplined engineering practice. By combining structured schemas, contextual personas, diverse few-shot demonstrations, targeted reasoning prompts, and automated validation, development teams can build robust pipelines capable of handling the inherent messiness of real-world data.
Shittu Olumide is a software engineer and technical writer focusing on the integration of emerging technologies and the simplification of complex technical concepts.