
Over the past two years, the landscape of intellectual property law has been repeatedly tested by the rapid rise of generative artificial intelligence. Rightsholders across various creative industries—ranging from bestselling authors and prominent journalists to major publishing houses—have filed a sweeping wave of lawsuits against the technology companies responsible for developing advanced AI models. These legal battles frequently center on the core data ingestion practices that power these systems, questioning whether scraping, downloading, and utilizing copyrighted works without authorization constitutes copyright infringement or falls under the legal protections of fair use.
Among the prominent technology companies targeted by these actions is Meta Platforms. The social media giant has found itself embroiled in a long list of legal challenges regarding its training procedures for its flagship Llama models. This scrutiny includes a high-profile class-action lawsuit originally initiated by well-known authors such as Richard Kadrey and Sarah Silverman. In their complaint, the authors accused Meta of unlawfully training its models on vast troves of pirated books acquired from online shadow libraries, and further alleged that the company actively shared those unauthorized files with other users on the BitTorrent peer-to-peer network during the acquisition process.
The Evolution of Meta’s Fair Use Defense
The legal dynamics of the dispute shifted significantly last summer when U.S. District Judge Vince Chhabria issued a ruling concluding that the actual AI model training conducted by Meta constituted fair use under copyright law. However, that ruling did not entirely clear the company of liability. It left the BitTorrent distribution and uploading claims as the last remaining live components of the litigation, keeping the spotlight firmly on how the datasets were technically acquired.
Earlier this year, Meta introduced a novel line of defense to address these lingering distribution claims. In a supplemental interrogatory response filed with the court, the tech firm argued that any uploading of pirated books that occurred while its systems were downloading files via BitTorrent was entirely "part-and-parcel" of a legitimate fair use purpose.
Elaborating on this argument, Meta asserted that BitTorrent served as a significantly more efficient and reliable means of obtaining massive data corpora compared to traditional download methods. In the specific case of repositories like Anna’s Archive, the company claimed it was the only practical way to acquire the materials in bulk. Because peer-to-peer networks inherently require participants to upload data to other network peers as they download, Meta contended that any subsequent sharing of files was simply an inherent, unavoidable characteristic of the BitTorrent protocol itself, rather than an intentional act of mass distribution designed to infringe copyright.
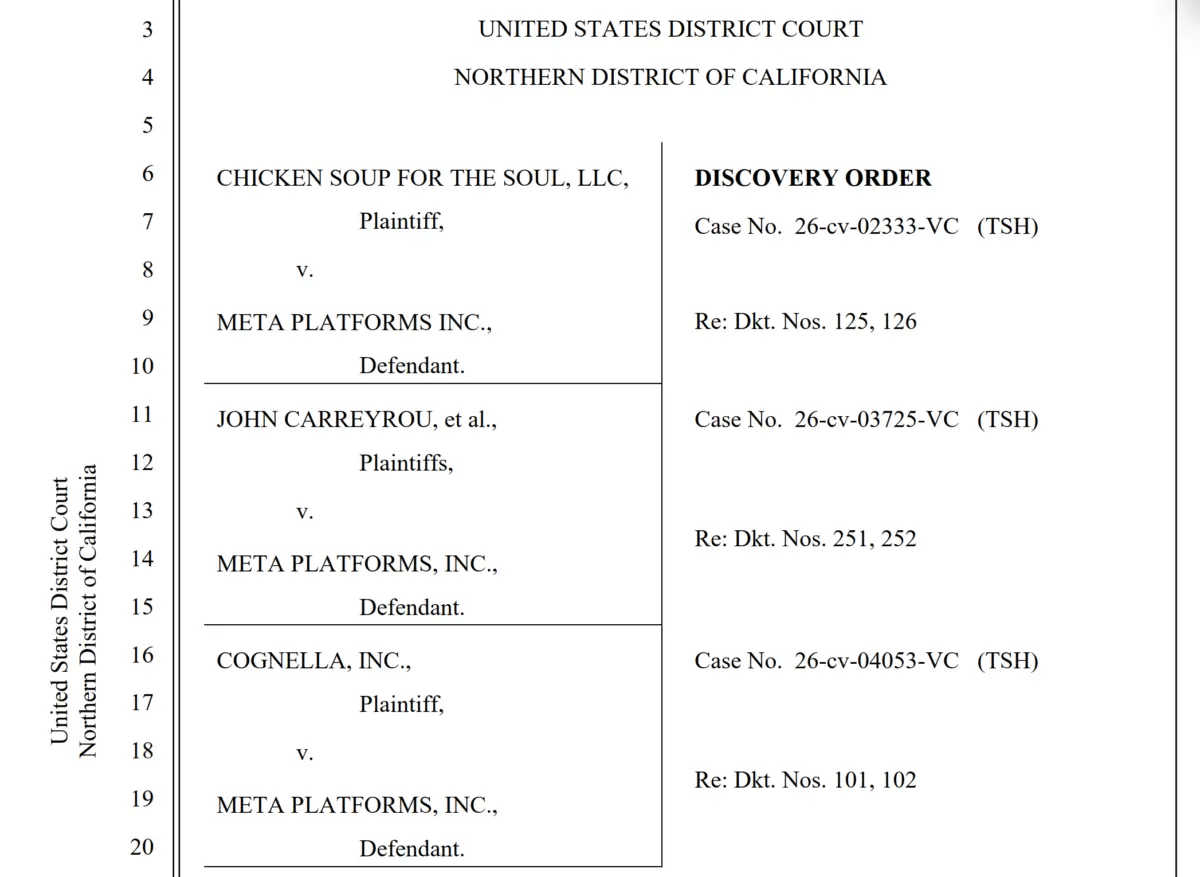
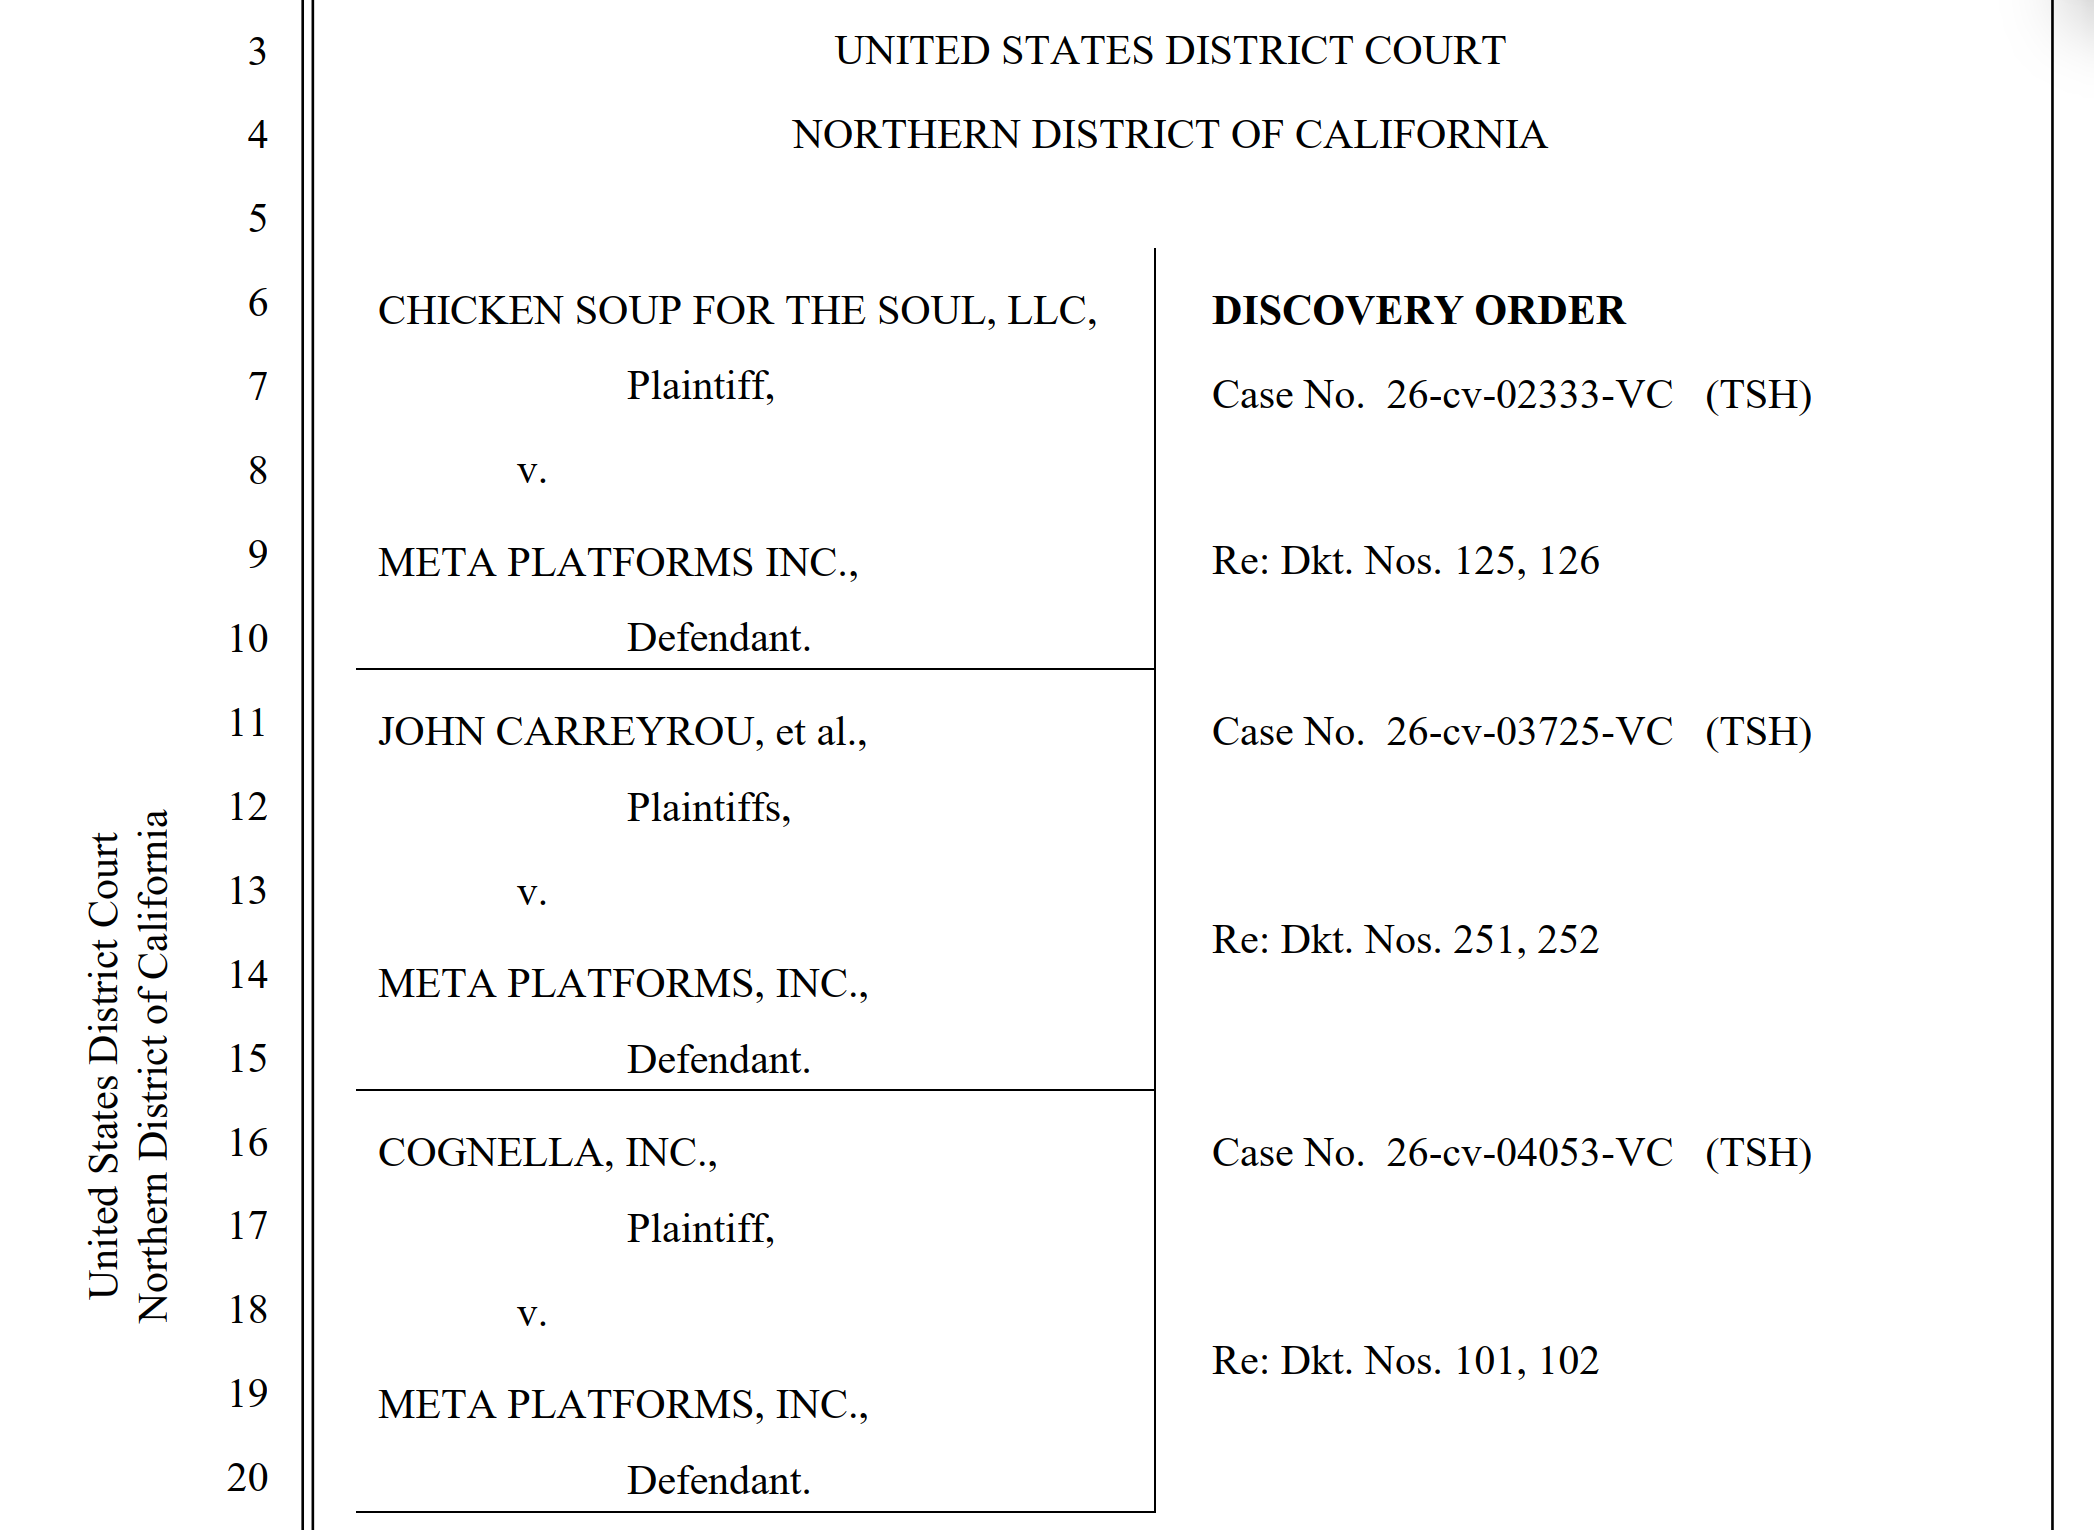
These specific BitTorrent-related claims are now being rigorously tested in three coordinated, related lawsuits assigned to Judge Chhabria. Filed by Chicken Soup for the Soul, academic publisher Cognella, and Cambronne Inc.—a company represented by journalist John Carreyrou—these combined actions target the exact same shadow library torrenting activities employed by Meta during its data collection phases.
Plaintiffs Seek Answers From AI Rivals
Rather than waiting indefinitely for Meta to produce exhaustive technical documentation detailing its internal BitTorrent client setup and configuration files, the publishing plaintiffs decided to cast a wider net. They sought to leverage information from two of Meta’s primary artificial intelligence competitors, hoping to gather industry benchmarks that could either support or disprove Meta’s necessity and inherent-behavior arguments.
In August, the publishers issued formal subpoenas to both OpenAI and Anthropic. The subpoenas demanded the identity, specific software versions, and configuration logs of every torrent client utilized by the two rival AI developers since 2019. Crucially, the requests specifically targeted any records indicating historical efforts or configurations aimed at preventing data uploading or seeding while utilizing peer-to-peer networks.
In the context of parallel copyright lawsuits spanning the AI industry, both OpenAI and Anthropic have previously acknowledged utilizing books sourced from shadow libraries to train their own systems. The publishers reasoned that if these competing companies had successfully configured their torrent clients to suppress uploading—thereby downloading the required training data without acting as active seeders—Meta’s foundational argument that seeding is an unavoidable technical necessity of the protocol would face severe legal jeopardy.
Arguing this point before the court, the publishers maintained that if OpenAI was capable of torrenting required datasets while actively suppressing its upload functions, then the network redistribution that Meta characterized as an inherent characteristic of the protocol was ultimately just a setting that Meta willingly chose not to change. This line of reasoning built upon an earlier breakthrough in the discovery phase of the litigation, which uncovered that a Meta engineer had previously written a custom script specifically designed to prevent seeding, while continuing to allow the downloading or leeching of files.
OpenAI and Anthropic Push Back Against Subpoenas
Rather than complying with the broad document demands, OpenAI and Anthropic strongly resisted the subpoenas. The AI competitors informed the court that probing the internal technical operations of rival companies was unnecessary and legally unwarranted. They argued that examining their own proprietary torrent client configurations would yield no relevant insight into Meta’s distinct technical practices or operational capabilities.
Attorneys representing Anthropic emphasized to the court that torrent clients are far from interchangeable tools. They highlighted that different software applications vary widely in their default upload parameters, the extent to which those default settings can be customized or reconfigured, and their technological capacity to suppress data transmission during and after a download cycle concludes. Consequently, Anthropic’s legal team argued that whatever settings Anthropic’s chosen client permitted or restricted demonstrated absolutely nothing about how Meta’s systems operated.
OpenAI echoed these exact sentiments in its own filings, pointing out to the presiding magistrate that the plaintiffs had produced no concrete evidence demonstrating that OpenAI had employed the exact same torrent clients or constructed comparable data corpora to those utilized by Meta.
Court Sides With AI Rivals on Subpoena Limits
The discovery dispute ultimately landed before Magistrate Judge Thomas Hixson, who issued a ruling siding with OpenAI and Anthropic. Without making any final determination on the underlying merits of Meta’s fair use or seeding arguments, the court concluded that the private torrent logs and internal operational records of competing AI developers did not constitute the appropriate or most reliable avenue for gathering evidence in the case.
In his written order, Judge Hixson noted that to the extent Meta’s fair use defense hinged on the technical assertion that its utilization of BitTorrent represented the only manner in which the protocol could possibly function, that assertion could be directly tested and evaluated by examining the BitTorrent software itself through expert analysis. Asking third-party competitors like OpenAI or Anthropic for their historical logs, the magistrate reasoned, would say very little about Meta’s specific technical architecture or the generalized capabilities of torrent client software.
The court further observed that any general user of a peer-to-peer network could theoretically be relevant under such a broad standard of discovery, prompting the question of why the plaintiffs’ own technical experts could not simply utilize standard torrent clients to demonstrate how the software can be configured. Furthermore, the court pointed out that questions regarding whether shadow library datasets could exclusively be acquired in bulk through torrenting could be addressed directly by communicating with the libraries themselves, rather than attempting to extract secondary operational data through rival technology corporations.
Focus Shifts to Meta’s Own Server Logs
While the court decisively ruled that seeking internal operational data from rival AI companies was off-limits, a markedly different standard was applied to Meta’s own internal data infrastructure. The legal boundaries regarding what Meta must disclose were drawn much closer to home.
In a related development concerning the class-action lawsuit led by Richard Kadrey and other authors, Judge Hixson granted a motion compelling Meta to produce comprehensive command history files for every server the company utilized during its torrenting operations. This expansive order explicitly encompasses all relevant virtual machines and Amazon Web Services instances employed by the tech giant.
Command history files function as systemic server logs that meticulously record every command entered by an operator during a session. For a machine dedicated to torrenting activities, these logs are expected to reveal critical operational details, including the exact method by which the torrent client software was installed, the configuration parameters applied, and any modifications made to upload and seeding settings over time.
This order stems from earlier procedural missteps earlier in the year, when Meta acknowledged that it had failed to produce certain relevant documents until after the established discovery deadline had formally elapsed. To remedy the procedural disadvantage imposed on the plaintiffs, Judge Chhabria granted the authors supplemental discovery privileges, specifically aimed at uncovering records that document how Meta’s torrent clients were configured and operated in practice.
Although Meta argued that the extensive log files it had already handed over to the plaintiffs were fully sufficient for legal evaluation, Judge Hixson rejected that position, ordering the company to surrender the detailed command histories. The plaintiffs hope that these granular server logs will finally provide definitive proof regarding which specific copyrighted works Meta acquired via torrenting networks. Whether the data will ultimately substantiate those claims remains to be seen.
For the time being, the central question of whether Meta could have successfully downloaded the contested books without simultaneously seeding them to the peer-to-peer network rests squarely in the hands of the plaintiffs’ technical experts. These experts will analyze Meta’s newly acquired server records, with their preliminary expert reports in the ongoing Meta cases scheduled for submission later this month.